Privoid Redact 4B
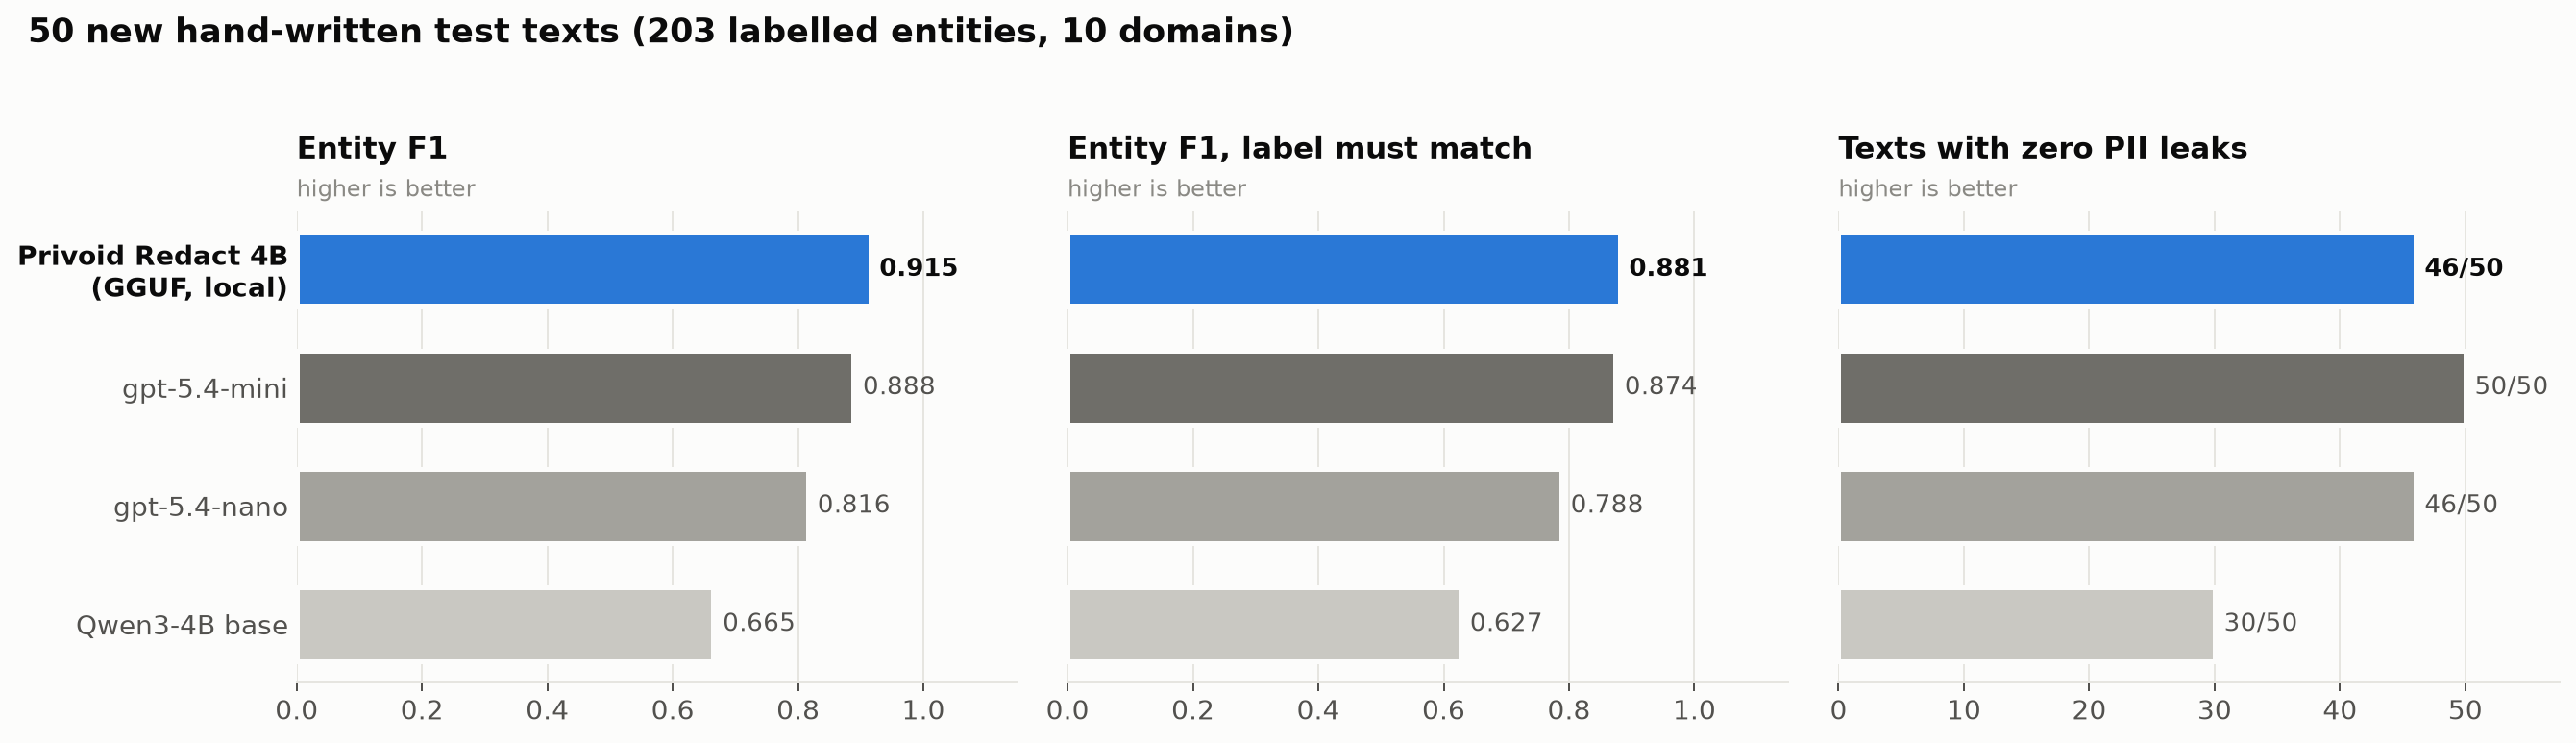
A 2.5 GB model that runs on your own machine and finds the personal data in any text: names, phone numbers, IDs, card and bank numbers, API keys, passwords, health details. On our 50 new test texts it scores a higher PII F1 than gpt-5.4-mini and gpt-5.4-nano, and nothing ever leaves your computer.
Head-to-head on 50 new texts
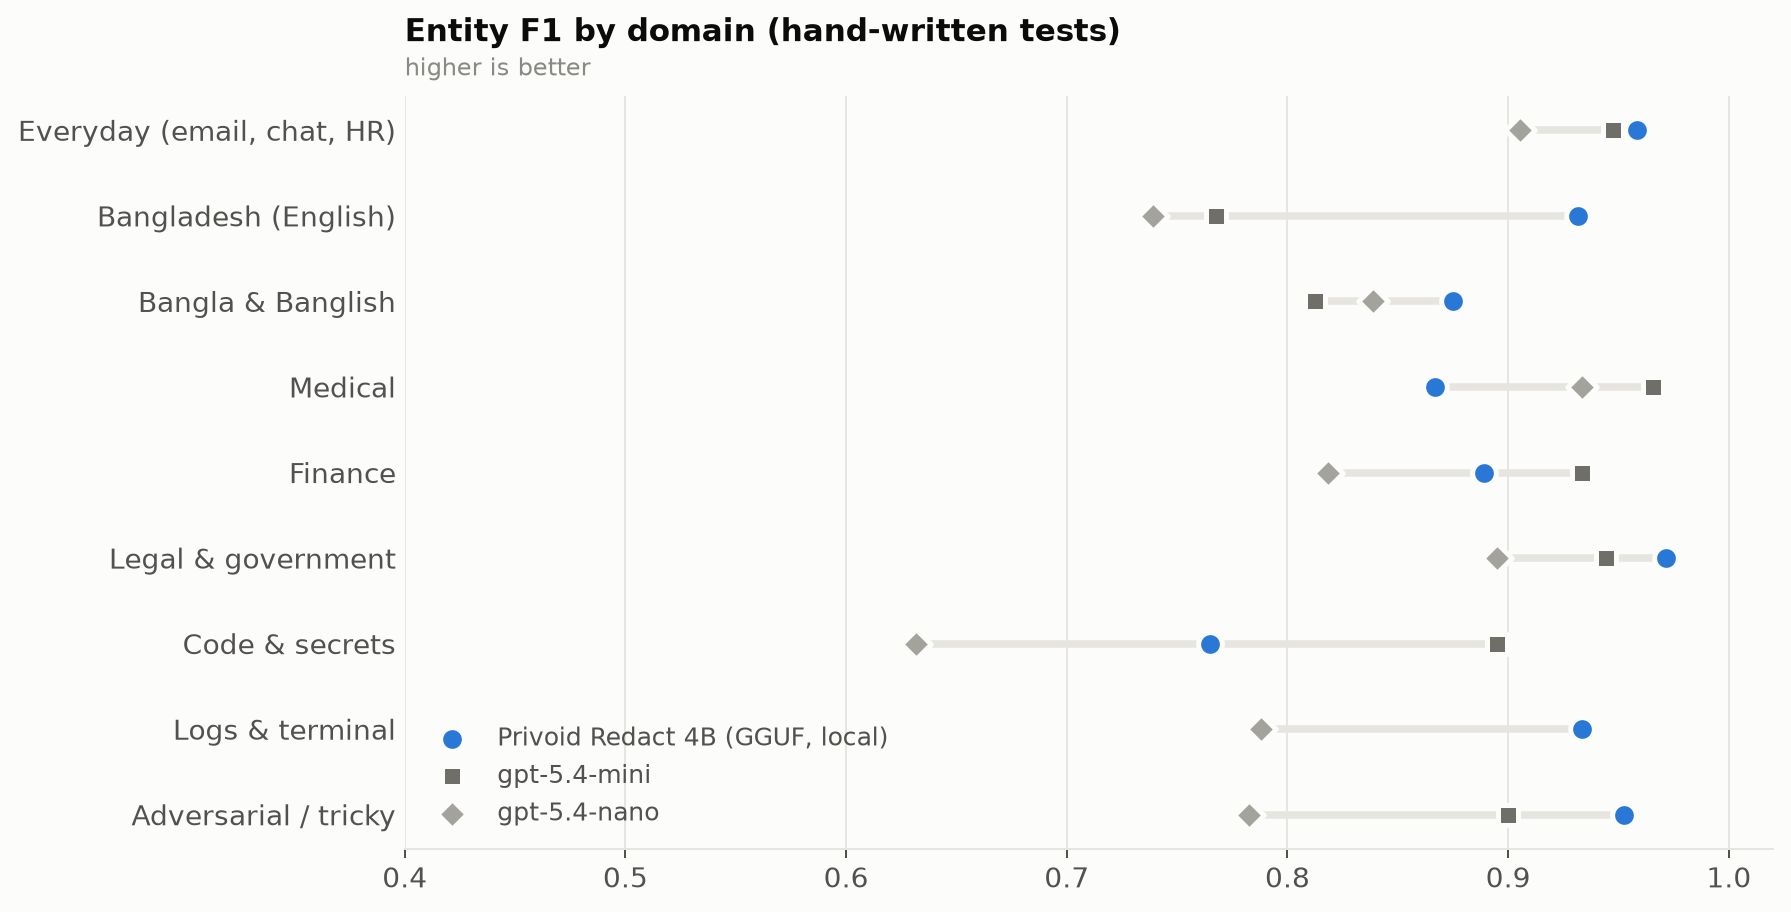
Hand-written for this evaluation and never seen in training: emails, chats, HR records, Bangladeshi documents, Bangla script, medical, finance, legal, code, logs and adversarial prompts. 203 labelled entities. Same prompt and scoring for every model.
Leak = a core PII item (name, contact, ID, financial, secret, health) left partly visible. OpenAI models called via API with reasoning_effort="low". gpt-5.4-mini is safer on leaks; Privoid Redact is more accurate overall and runs offline. All raw predictions are in the model repo.
Charts
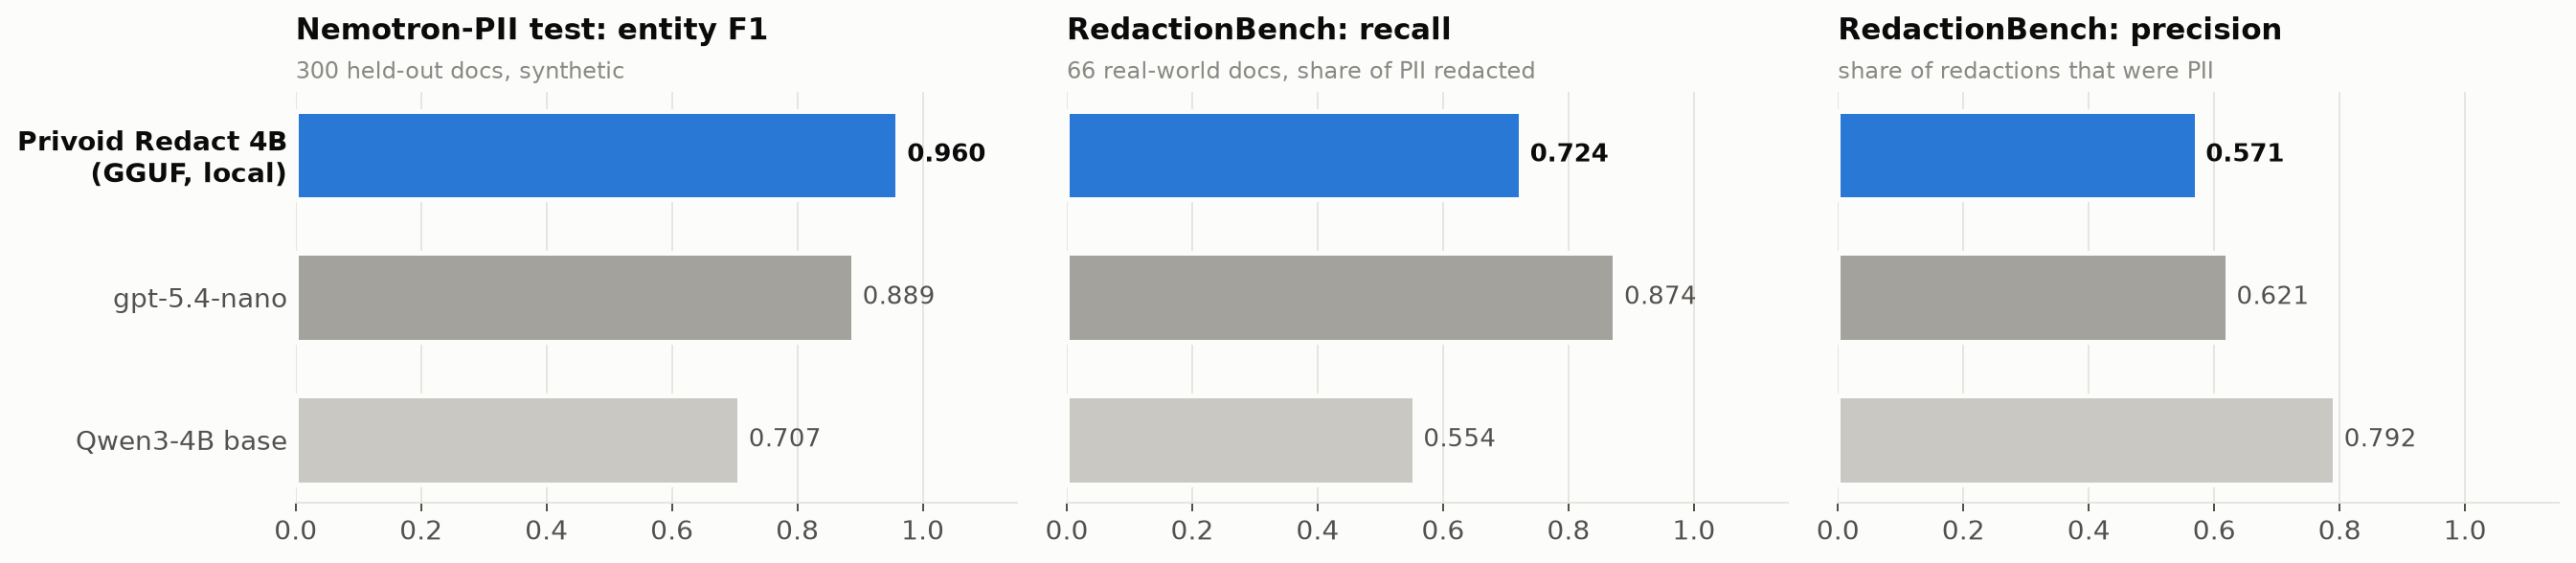
Including the parts where it loses: real-world documents (RedactionBench), code and logs.
Explore every test
Pick a test and see exactly what each model redacted.
Run it locally in four lines
Works with llama.cpp, LM Studio, Ollama and llama-cpp-python. CPU is fine; a GPU is faster.
pip install llama-cpp-python huggingface_hub

from huggingface_hub import hf_hub_download
from llama_cpp import Llama
repo = "Siyam/Privoid-Redact-4B-GGUF"
llm = Llama(model_path=hf_hub_download(repo, "privoid-redact-qwen3-4b-instruct-2507-Q4_K_M.gguf"), n_ctx=4096)
exec(open(hf_hub_download(repo, "redact_core.py")).read())   # SYSTEM_PROMPT, parse_entities, mask_text

text = "Call Rahim Uddin on +880 1712-345678 or rahim.uddin91@gmail.com"
out = llm.create_chat_completion([{"role": "system", "content": SYSTEM_PROMPT},
                                  {"role": "user", "content": text}], temperature=0)
print(mask_text(text, parse_entities(out["choices"][0]["message"]["content"], text)))
# → Call [FIRST_NAME] [LAST_NAME] on [PHONE_NUMBER] or [EMAIL]
Or: llama-server -hf Siyam/Privoid-Redact-4B-GGUF:Q4_K_M · ollama run hf.co/Siyam/Privoid-Redact-4B-GGUF:Q4_K_M